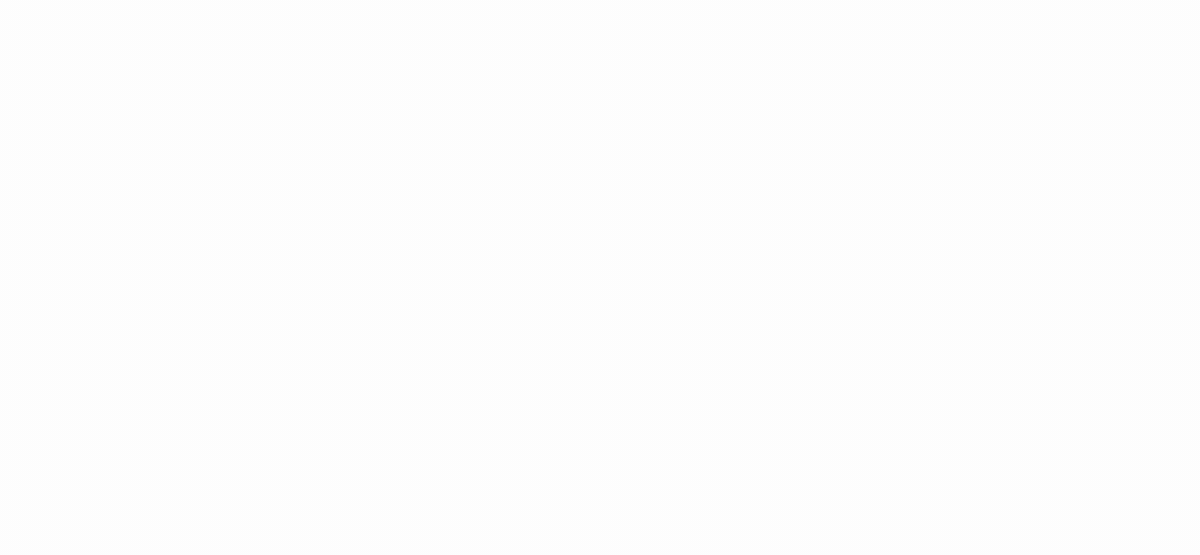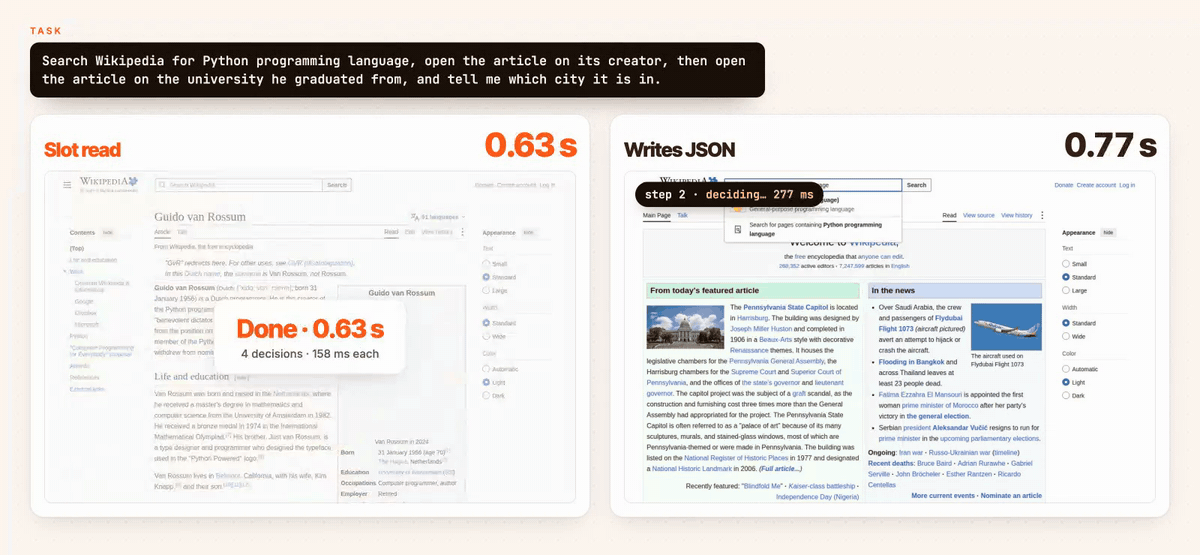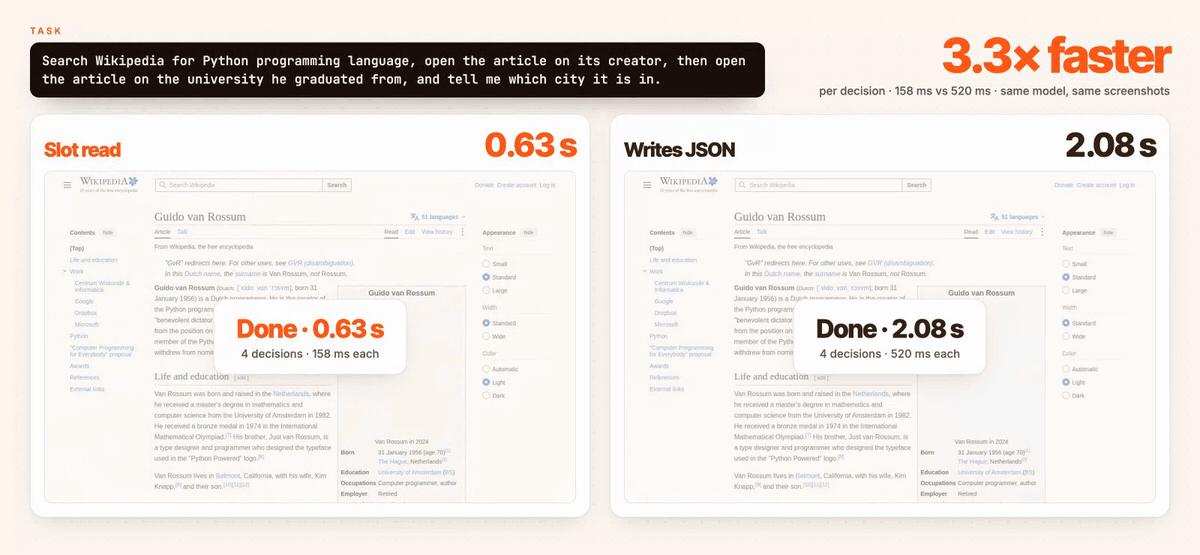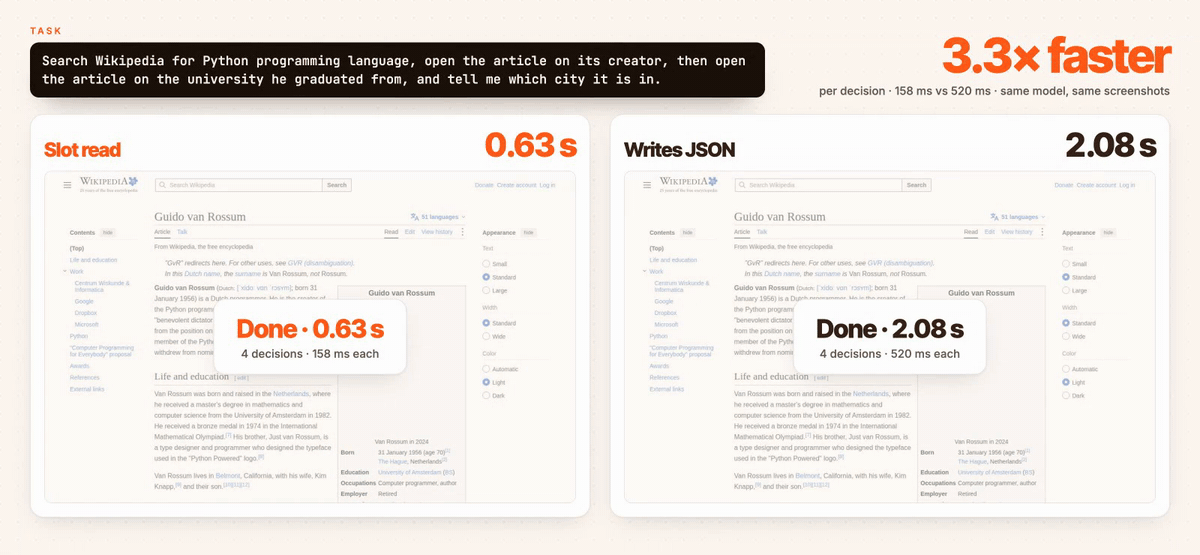
This post is a mirror of my blog post on Huggingface Blog.
TLDR: System-one decision models (like Jev) select categorical answers without generating text. But Computer-use agents need more than categories; they need precise coordinates and actions. In this post, we extend this idea to continuous-valued predictions by reading coordinate distributions directly from an LLM instead of generating them. Fine-tuning a multimodal LLM this way yields >3x faster computer-use grounding than non-thinking baselines and 25x faster than the same model with reasoning on.
Published models - GUI-Decisions-31B , GUI-Decisions-2B , Try them live here : GUI-Decisions Space
Current-generation computer-use agents are frustratingly slow, making the overall user experience bad. When I first heard about Jev, the concept of super-fast System One decision models blew my mind. My first thought was: Could we make computer-use agents just as fast?.
That pursuit led to Prototype SystemOne, which is a library for building System One decision models on top of any LLM. But it still missed one crucial piece: predicting continuous values like coordinates and bounding boxes. This blog explores that missing piece of how we can extend System-One decision-making to coordinates, eliminate much of the autoregressive decoding overhead, and build substantially faster GUI grounding systems
The ingredients needed are simple:
- It should be Fast: A major chunk of the latency in a GUI grounding step is spent decoding a JSON object or a tool call token by token,
something like
{"action": "click", "point": [412, 288]}( with reasoning). So if we can predict these actions and coordinates in a single pass without needing to decode them as text tokens, we can get a significant speedup. - It should be Hybrid: Because we can’t truly get rid of decoding; for an action like “type”, we need the text tokens. So we need a hybrid approach that decodes text tokens when needed and predicts coordinates and bounding boxes in a single pass when not.
- It should be Extensible: to leverage and extend existing multimodal LLMs already trained for computer-use/GUI grounding tasks.
This post walks through how we got there.
Figure 1: Writing vs reading a decision.
1. Existing LLMs are already decision models (zero-shot)
Zero-shot classification using encoder models has been around for a while. Jev’s recent popularity has renewed interest in this approach. Not only for encoder models, but this has brought in a perspective shift for decoder (LLMs) models. For simple classification tasks, do we even need to spend latency on decoding / generating texts ?
Many questions an application asks a model have a closed answer: is this urgent?, which team handles this ticket?, does the user want to cancel? For these, you don’t need the model to write an answer. You need its opinion, as a probability over the allowed answers.
This can be elicited from an existing LLM by building the prompt so it ends exactly where the answer goes, and reading one next-token distribution:
<system: the questions, each with single-token labels>   A: billing  B: technical  C: other
<user: the ticket>
<assistant>department: __        ← P(" A"), P(" B"), P(" C") at this position = the answer
Nothing is generated. The labels are single tokens (yes/no, A–Z, 1–9), and the
probabilities over them are the answer. Inference engines like vLLM / Sglang can return log-probabilities for exactly these token IDs, so one forward pass gives a calibrated-ish distribution over the options.
There are many recent community packages, including official ones that exposes a JEV-like system-one decisions API for any vLLM or SGLang server using this approach.
Interestingly, the LLM zero-shot results are comparable to JEV on the typed-decisions benchmark (2,000 decisions, evaluation results from SystemOne) :
| model | typed acc | ECE (calibrated) | ms / 5-question case |
|---|---|---|---|
| Gemma 4 31B, zero-shot | 0.709 | 0.105 | 81 |
| Qwen3.5-35B-A3B, zero-shot | 0.672 | 0.091 | 206 |
| gpt-oss-20b, zero-shot | 0.597 | 0.055 | 42 |
| TypeSafe Jev 1.13 (published) | 0.727 | 0.144 | 710 |
Figure 2: Several questions, one prefill.
1.1. Training LLMs to be decision models
Zero-shot reads are good. A small LoRA makes them much better. Because the “answer” is a distribution over a handful of label tokens, training is just cross-entropy on that distribution at the answer position.
| Gemma 4 31B on typed-decisions | accuracy | Brier |
|---|---|---|
| zero-shot | 0.702 | 0.111 |
| + LoRA, RLCD objective | 0.785 | — |
| + LoRA, plain cross-entropy | 0.791 | 0.041 |
(We tried an RL objective (RLCD) and plain cross-entropy. Cross-entropy did as well or better, so that’s what we use from here on.)
This is the key design choice: the model now learns to put probability mass on the right label at a fixed position instead of writing the answer. Now we have a way to fine-tune an existing LLM to be a decent decision model. But we need to go beyond categories/classification to predict continuous values like coordinates to build computer-use agents. Which brings us to the next section.
2. Slot reading: Predict Coordinates without decoding
A computer-use step needs more than just classification, It needs an action (click, type, scroll…), and usually a point on the screen. A point is two continuous values - x and y coordinates. The normalized coordinates are predicted as values between 0 and 1. One way to approximate these continuous values is to discretise them into a finite number of bins.
Slots:
We give the assistant turn a fixed template of slots, each ending in a placeholder token:
action: ___ x: ___ y: ___ x2: ___ y2: ___ key: ___ sdir: ___ samt: ___
Each slot’s answer is the next-token distribution at the token before its placeholder. The placeholders let every slot be potentially read from one prefill: no slot waits for another to be generated. (In practice we send one request per slot in parallel and let vLLM’s / SGlang’s prefix cache share the screenshot and prompt.)
Figure 3: Slot reading.
The action slot is easy: its labels are words like click. The coordinates are the interesting part.
How do you make a language model output a number in one token?
Numbers as bins
We split each axis into bins and give every bin its own single-token label. The model’s answer
for x is a distribution over bins. We read it out as the peak, refined by its neighbours (or the
expected value). Training uses soft ordinal targets: a small Gaussian over neighbouring bins, so
“one bin off” is penalised less than “half a screen off”.
Figure 4: Where the model wants to click: a real read of the 256-bin x and y slots.
This leads us to two important questions: how many bins and which tokens from existing vocabulary to use as bins ?
3.1 Coarse to fine: xc, then x
My first experiment was a method borrowed from robotics, where action heads often predict a coarse bin and then a refinement (e.g. binned SE(2) trajectories). Each number gets two slots:
xc: ___   ← the tens digit: which tenth of the screen (10 labels: 0–9)
x:  ___   ← the fine position: 256 bins over the full axis
At read time, we fuse them: the fine distribution is multiplied by the coarse slot’s probability for the tenth each bin falls in, then refined around the peak. The coarse slot acts as a prior that keeps the fine read from jumping to the wrong side of the screen.
I know that Occam wouldn’t be happy with this approach. To make him happy we test a simpler alternative.
Figure 5: How a number becomes one token (5 steps, ending with coarse to fine).
3.2 Fine only: 256 bins in one slot
The simpler alternative is one slot per number with 256 bins. This approach is inspired by GPC-1’s 101 Bin approach. The catch is which tokens to use as the 256 labels:
- Ordinary words (
apple,river, …) as bins never learned: 0.6% accuracy on ScreenSpot. The model has to unlearn 256 word meanings and has no sense that bin 117 sits next to bin 118. With a coarse slot in front (3.1), the same word bins do learn. Combining with coarse slots seem to condition the fine slots for better learning. - Byte-like tokens (ASCII characters plus two-letter tokens like
ab,zz) work well. They carry little meaning to unlearn, and we chose them to have low embedding similarity to each other (mean cosine 0.14 for the 256-label set), so the model can separate them.
We also compared our 256-bin approach to 101 bins of single-character labels of GPC-1
Figure 6: Choosing bin labels.
Our arms, all LoRA on Gemma 4 31B:
| arm | coarse slot | bins | labels |
|---|---|---|---|
| A | yes | 256 | words |
| F | yes | 256 | bytes |
| E | no | 256 | bytes |
| B+ | no | 101 | single characters (GPC-1 grid) |
3.3 Results
Figure 7: Accuracy summary.
What we took away:
- Occam was right. Coarse-to-fine isn’t needed once the labels are right. With byte labels, the single 256-bin slot (E) matches or beats coarse + fine (F). It’s also simpler and ~15–20 ms faster (fewer slots). Coarse-to-fine mainly rescues bad labels (A).
- 256 bins outperform 101 on agent steps (+9.5 points), and were comparable on clicks. Clicks only need to land inside an element. Agent steps (swipe ends, small targets) reward precision.
Latency
Each measurement is a single end-to-end computer-use step with a cold screenshot, an idle GPU, and no request batching — RTX PRO 6000, vLLM, Gemma 4 31B NVFP4. Median across 80 screenshots:
| how the step is decided | time per step | vs slots |
|---|---|---|
| slot read (E) | 146 ms | — |
| slot read, coarse to fine (A / F) | 159–163 ms | +~15 ms |
vanilla, native [y, x] JSON (~20 tokens) |
472–546 ms | ~3.5× slower |
| vanilla, pixel JSON (~30 tokens) | 704 ms | 4.8× slower |
| vanilla + thinking (130–230 tokens) | 2.6–3.1 s (up to 7 s on a hard step) | ~20–25× slower |
“Search Wikipedia for Lewis Hamilton and tell me which Formula One team he drives for.” Both correct (Ferrari): slots 4.2 s, vanilla with thinking 30.5 s.
Results with smaller models:
We validated the same recipe on a 2B GUI model (GUI-Owl-1.5-2B, computer-use data only):
| computer-use step (clean, 1,600) | ScreenSpot clicks | time per step | |
|---|---|---|---|
| GUI-Owl-2B + slots | 0.626 | 0.770 | 133 ms |
| GUI-Owl-2B vanilla (its own tool-call format), native resolution | 0.626 | 0.645 | 444 ms |
| GUI-Owl-2B vanilla, same capped images | 0.610 | 0.626 | 225 ms |
Same accuracy as vanilla GUI-Owl at native resolution, at 30% of the latency. (Vanilla GUI-Owl’s click numbers use its agent prompt, not its dedicated grounding prompt.)
Caveats
- Of course, this alone doesn’t completely fix computer-use agents’ latency issue: it just speeds up grounding, and latency would increase as turns increase in an agentic session; multi-turn/complex tasks would also require reasoning for the agents to do well. These still add significant latency.
- Other changes that made it read fast. The first version took ~240 ms per step. Three fixes brought it to ~146 ms:
| fix | saved |
|---|---|
| raise vLLM’s per-request label-id cap from 128 to 256 (one request per 256-bin slot, not two) | ~55 ms |
run 8 API-server processes (--api-server-count 8): the default single process serialized our parallel slot requests |
~45–55 ms |
| send screenshots as JPEG at the model’s input size, not full-size PNG | ~15–25 ms server side, ~110 ms client side |
What’s next
- Faster text steps. Typing and answering still wait for the base model to write. We want to overlap that call with the slot read.
- Rethinking reasoning: Decision models have successfully raised a contrarian question: Is reasoning necessary for all the tasks? We should probably explore that further for multi-turn computer use agent tasks and do away with reasoning for the steps that don’t truly need it. **
- Multi-step computer use : As mentioned in the caveats, this blog post focuses only on speeding up the grounding step of the computer use task. Combining this with approaches to train a multi-step computer-use agent would be an interesting next step.
Appendix:
A.1 setup
- Model. Gemma 4 31B (bf16 for training, NVFP4 for serving with vLLM 0.30). LoRA r16 on the language model.
- Training. Full-vocabulary cross-entropy on soft ordinal targets, loss normalized per number, one adapter for all tasks.
- Data. AGUVIS (stage 2), Wave-UI clicks and boxes, RefCOCO (boxes, masks). Evaluation on ScreenSpot, held-out AGUVIS (a clean set from rows 6,000+ of every source), RefCOCO val, COCO val2017 and Fashionpedia.
A.2. Beyond clicks: boxes and segmentation
I wanted to experiment with extending the slot reading approach to bounding boxes and segmentation masks, with the following templates:
box:   cx: ___ cy: ___ w: ___ h: ___                 (sizes on a log scale)
mask:  cx: ___ cy: ___ r0: ___ r1: ___ … r23: ___    (24 rays from a centre)
- Boxes are a centre plus a size. The sizes are log-warped, because UI elements and objects span three orders of magnitude.
- Masks are a centre plus 24 ray lengths (“how far the object reaches in each direction”), drawn as a polygon. The centre is the point deepest inside the object, so it always falls inside it.
Figure 9: Boxes and masks as slots.
The 24-ray polygon gets the object’s extent roughly right but misses thin parts. SAM 2 is very good at edges when told where to look. So we read a box and a centre in one pass, and hand them to SAM 2 as its prompt.
Figure 10: Box → SAM 2 → mask.
Results
Boxes on general objects. The first box task was trained on UI elements only. On photos it found the right object (centre inside the object 97% of the time) but made boxes far too small. Adding 5k RefCOCO photo boxes (E3) fixed that, without hurting computer use (clean test: 0.659 vs 0.654):
| box IoU | UI boxes only | bytes-GPC | UI boxes + RefCOCO photo boxes |
|---|---|---|---|
| RefCOCO val photos (3,811) | 0.249 | 0.400 | 0.770 (IoU ≥ 0.5: 92%) |
| COCO val2017 (photos never used, category prompts; 1,000) | 0.309 | 0.448 | 0.742 |
| Fashionpedia (a new domain; 1,000) | 0.326 | 0.514 | 0.616 |
| ScreenSpot UI elements (1,272) | 0.440 | 0.479 | 0.467 |
Masks. On their own, the 24 rays reach ~0.56 mIoU. The polygon gets the extent roughly right but cuts off thin parts (legs, arms). Handing our box and centre to SAM 2 as a prompt fixes the edges:
| mask mIoU | RefCOCO val (1,000) | COCO val2017 (500) |
|---|---|---|
| our 24-ray polygon | 0.56 | 0.54 |
| SAM 2 from our polygon’s box (grown 40%) + centre | 0.756 | 0.704 |
| SAM 2 from E3’s box (grown 20%) + centre | 0.792 | 0.763 |
| SAM 2 from the true box (ceiling) | 0.861 | 0.850 |
SAM 2 adds ~20 ms per image plus a few ms per prompt.
Citation
If you found this useful, please cite it as:
Umapathi, Logesh Kumar. (Oct 2026). “Stop Decoding Coordinates: 3.5× Faster Computer-Use Grounding”. logeshumapathi.com. https://logeshumapathi.com/blog/2026/10/06/slot-reading.html
@article{umapathi2026slotreading,
  title   = "Stop Decoding Coordinates: 3.5× Faster Computer-Use Grounding",
  author  = "Umapathi, Logesh Kumar",
  journal = "logeshumapathi.com",
  year    = "2026",
  month   = "Oct",
  url     = "https://logeshumapathi.com/blog/2026/10/06/slot-reading.html"
}


